DiT
This page covers the diffusion-based models in Simulusion: DDPM for image generation, DiT for scalable transformer-based diffusion, and DIAMOND for diffusion world models in reinforcement learning.
Based on papers:
- Denoising Diffusion Probabilistic Models (Ho et al., 2020)
- Scalable Diffusion Models with Transformers (Peebles & Xie, 2023)
- DIAMOND: Diffusion as a Model of Environment Dreams (Alonso et al., 2024)
See it in action
Trained from scratch in one to two hours on a 4 GB laptop GPU with
python demos/dit_demo.py train, then recorded with python demos/dit_demo.py record.
More clips are in the gallery.
Overview
Diffusion models learn to generate data by reversing a gradual noising process. In Simulusion, diffusion models serve two purposes:
- Image/video generation (DDPM, DiT): High-quality unconditional or conditional sample generation.
- World models for RL (DIAMOND): Diffusion-based dynamics models that predict future observations.
graph LR
    A["Data x₀"] --> B["Forward: q(x_t|x₀)"]
    B --> C["..."]
    C --> D["x_T ~ N(0, I)"]
    D --> E["Reverse: p_θ(x_{t-1}|x_t)"]
    E --> F["..."]
    F --> G["Generated x₀"]
DDPM: Denoising Diffusion Probabilistic Models
Forward Process
The forward (diffusion) process gradually adds Gaussian noise to data over T
timesteps according to a fixed variance schedule:
We can sample x_t directly from x_0:
where α_t = 1 - β_t and \bar{α}_t = ∏_{s=1}^{t} α_s. Using the
reparameterization trick:
Reverse Process
The reverse process learns to denoise. Starting from pure noise x_T ∼ N(0, I):
Training Objective
The simplified DDPM loss trains the model to predict the noise ε at each timestep:
x0 = batch  # clean images
t = randint(0, T)  # random timestep
eps = randn_like(x0)  # random noise
xt = sqrt(alpha_bar[t]) * x0 + sqrt(1 - alpha_bar[t]) * eps
eps_pred = model(xt, t)  # predict noise
loss = mse(eps_pred, eps)  # simple noise-prediction loss
loss.backward()
Sampling
x = torch.randn(shape)  # pure noise
for t in reversed(range(T)):
    eps_pred = model(x, t)  # predict noise
    x = (x - sqrt(1 - alpha_bar[t]) * eps_pred) / sqrt(alpha_bar[t])
    if t > 0:
        x += sigma[t] * torch.randn_like(x)
return x  # generated image
DiT: Diffusion Transformer
DiT replaces the U-Net backbone with a Vision Transformer for noise prediction, providing better scalability and global context.
Architecture
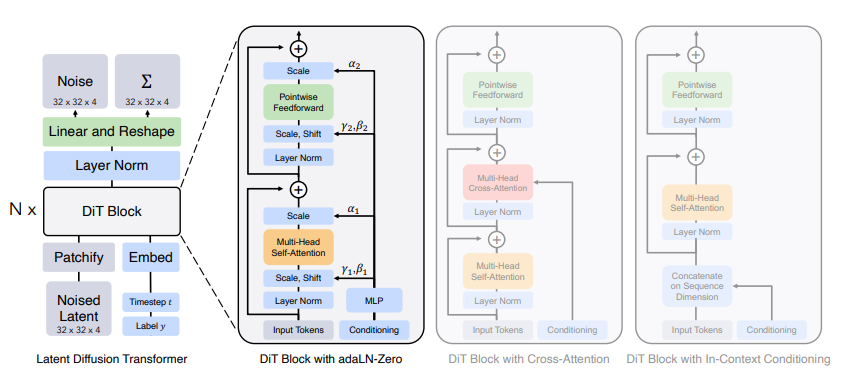
graph TD
    A["Noisy latent x_t"] --> B["Patchify + fixed sin-cos pos embed"]
    C["Timestep t"] --> D["Timestep embedder"]
    Y["Class label y"] --> Z["Label embedder (+ null token)"]
    D --> E["c = t_emb + y_emb"]
    Z --> E
    E --> F["DiT Block × depth (adaLN-Zero)"]
    B --> F
    F --> H["Final layer: adaLN + linear → p·p·2C"]
    E --> H
    H --> I["Predicted noise ε_θ and covariance Σ_θ"]
adaLN-Zero conditioning
Conditioning is the sum of the timestep and class embeddings. A single
SiLU → Linear per block regresses six vectors from it — shift, scale and
gate for each of the attention and MLP sub-layers (6 × hidden; vanilla
adaLN uses 4 × because it has no gates).
The gates are zero-initialised, so every block begins as the identity function. Figure 5 of the paper shows this is not a detail: adaLN-Zero reaches roughly half the FID of in-context conditioning at 400K steps, and clearly beats vanilla adaLN, which is otherwise the same block.
Model presets
Table 1 configs, selected by name and patch size:
from simulusion import DiT, dit_preset_config

model = DiT.from_config(dit_preset_config("DiT-XL", patch_size=2))| Preset | Layers | Hidden | Heads | Params (/2) |
|---|---|---|---|---|
DiT-S |
12 | 384 | 6 | 33M |
DiT-B |
12 | 768 | 12 | 130M |
DiT-L |
24 | 1024 | 16 | 458M |
DiT-XL |
28 | 1152 | 16 | 675M |
Patch size is the other axis of the design space (2, 4, 8). Halving it quadruples the token count and so the Gflops, which Figure 8 identifies — not parameter count — as what actually drives FID.
Classifier-free guidance
The label embedder holds num_classes + 1 rows; the extra one is a learned null
token that class_dropout_prob randomly substitutes during training. At sampling
time:
out = model.forward_with_cfg(x_t, t, y, cfg_scale=1.5)which computes ε(x,∅) + s·(ε(x,y) − ε(x,∅)). Guidance is what takes DiT-XL/2
from FID 9.62 to 2.27 in Table 2. Pass guided_channels=3 to reproduce the
appendix's subset-of-channels variant.
Output channels
With learn_sigma=True (the default, paper 3.1) the model emits 2C channels:
the predicted noise followed by the diagonal covariance parameterisation. The
built-in training loop applies L_simple to the noise half only — training
Σ_θ needs the full variational bound, which is not implemented here. Set
learn_sigma=False for a strictly ε-only model.
Patch Embedding
The input x_t ∈ ℝ^{C×H×W} is split into patches of size P and linearly embedded:
For a 32×32 CIFAR-10 image with P=4: 64 tokens of dimension D.
Timestep Conditioning (AdaLN)
DiT uses Adaptive Layer Normalization (AdaLN) to condition on the diffusion
timestep. The timestep embedding predicts the scale γ and shift β for each
block's layer norm:
| Variant | Scheme | Parameters | Speed |
|---|---|---|---|
| AdaLN | γ, β per block | Low | Default |
| AdaLN-Single | Shared γ, β | Very low | Fastest |
| AdaLN-Diagonal | γ, β + diagonal scaling | Medium | Medium |
DiT Block
No cross-attention — DiT is typically unconditional or class-conditional via AdaLN.
Training
from simulusion import DiTConfig, get_dit_config

cfg = get_dit_config(
    DATASET="CIFAR10",
    BATCH=128,
    EPOCHS=100,
    IMG_SIZE=32,
    WIDTH=384,
    DEPTH=6,
)
Sampling (Generation)
# Start from random noise, iteratively denoise
for t in reversed(range(T)):
    ε = model(x_t, t)  # Predict noise
    x_{t-1} = x_t - sqrt(1-alpha_bar_t) * ε
Classifier-Free Guidance
For conditional generation:
where w is guidance weight (typically 1-10).
DIAMOND: Diffusion World Models
DIAMOND applies diffusion models to world modeling for reinforcement learning. Instead of predicting latent states (Dreamer) or discrete tokens (IRIS), it predicts future observations using a diffusion denoising process.
Architecture
graph TD
    A["Past 4 frames"] --> B["Cond. encoder"]
    C["Action a_t"] --> B
    B --> D["Conditioning embedding c"]
    E["Noisy next frame x_t + ε"] --> F["Diffusion UNet"]
    D --> F
    F --> G["Denoised next frame x̂_t"]
    G --> H["Reward/Termination model"]
    H --> I["r̂_t, γ̂_t"]
    G --> J["Actor-Critic"]
Key Components
| Component | File | Description |
|---|---|---|
DDPM |
diffusion/DDPM.py |
Basic DDPM model and scheduler |
DiT |
diffusion/DiT.py |
Diffusion Transformer |
DiffusionUNet |
diffusion/diamond_diffusion.py |
Conditional UNet for DIAMOND |
EDMPreconditioner |
diffusion/diamond_diffusion.py |
EDM-style noise preconditioning |
EulerSampler |
diffusion/diamond_diffusion.py |
Fast ODE-based sampling |
RewardTerminationModel |
diffusion/reward_termination.py |
Reward and termination prediction |
ActorCriticNetwork |
diffusion/actor_critic.py |
Policy and value in imagination |
EDM Preconditioning
DIAMOND uses the EDM (Elucidating Diffusion Model) formulation:
This ensures the model always receives inputs scaled to unit variance and predicts a scaled output that works well across all noise levels.
Sampling
DIAMOND uses Euler sampling with very few steps (default 3) for fast inference:
x = noise * sigma_max
for sigma in sigmas[:-1]:
    denoised = model(x, sigma, cond)
    d = (x - denoised) / sigma
    x = x + d * (sigma_next - sigma)
return denoised
Usage in Simulusion
DiT quick start
from simulusion import DiTConfig, get_dit_config

cfg = get_dit_config(DATASET="CIFAR10", BATCH=128, EPOCHS=100, IMG_SIZE=32)
DIAMOND quick start
from simulusion import DiamondConfig

cfg = DiamondConfig(preset="small")  # small, medium, large
cfg.game = "Breakout-v5"
cfg.obs_size = 64
DIAMOND CLI
simulusion train diamond --config simulusion/configs/experiments/diamond.yaml \
    preset=small seed=1
Or directly:
python -m simulusion.training.train_diamond --game Breakout-v5 --preset smallDIAMOND Training Loop
for epoch in range(num_epochs):
    # 1. Collect real experience
    for step in range(environment_steps_per_epoch):
        action = select_action(obs)
        next_obs, reward, done = env.step(action)
        buffer.add(obs, action, reward, done, next_obs)
        obs = next_obs

    # 2. Train diffusion world model
    batch = buffer.sample(batch_size)
    loss = train_diffusion_step(batch)

    # 3. Train reward/termination model
    loss_r = train_reward_model(batch)

    # 4. Train actor-critic in imagination
    for step in range(imagination_horizon):
        action = actor(obs, hidden)
        next_obs = diffusion_model(obs, action, cond)
        reward = reward_model(next_obs)
        hidden = update_hidden(hidden, action, next_obs)
    actor_loss, critic_loss = compute_ac_loss(imagination_trajectory)
See Configs for the full DiTConfig and DiamondConfig field reference with defaults. |
Sampling Methods
| Method | Steps | Quality | Speed |
|---|---|---|---|
| DDPM | 1000 | Best | Slow |
| DDIM | 50–100 | Good | Fast |
| Euler | 3–10 | Fair for RL | Very fast |
| DPM-Solver | 10–20 | Excellent | Fast |
Comparison: DiT vs CNN-Based Diffusion
| Aspect | U-Net (DDPM) | DiT (Transformer) |
|---|---|---|
| Architecture | CNN with skip connections | ViT |
| Global attention | Limited | Full |
| Scalability | Medium | High |
| Quality | Good | Slightly better |
| Compute | Efficient | Higher |
Common Pitfalls
Slow sampling
DDPM with 1000 steps is too slow for RL training loops.
Fixes:
- Use Euler sampler with 3–10 steps (DIAMOND default)
- Use DDIM for higher quality with ~50 steps
Training instability
Diffusion UNets can produce NaN during training.
Fixes:
- Enable gradient clipping
- Use EDM preconditioning
Blurry generations
Low sampling steps produce blurry results.
Fixes:
- Increase
num_sampling_steps - Add classifier-free guidance
- Train with more diffusion timesteps
See Also
- Dreamer — continuous world model alternative using RSSM
- IRIS — discrete world model alternative using transformers
- Vision Components — diffusion model components (PatchEmbed, DDPM)
References
- Ho, J., Jain, A., & Abbeel, P. (2020). Denoising Diffusion Probabilistic Models. NeurIPS 2020.
- Peebles, W., & Xie, S. (2023). Scalable Diffusion Models with Transformers. ICCV 2023.
- Alonso, E., et al. (2024). DIAMOND: Diffusion as a Model of Environment Dreams. ICLR 2024.
- Song, J., Meng, C., & Ermon, S. (2021). Denoising Diffusion Implicit Models. ICLR 2021.
- Karras, T., et al. (2022). Elucidating the Design Space of Diffusion-Based Generative Models. NeurIPS 2022.
Updated Oct 11, 2026